AI Agents
AI on Kubernetes: From Inference to Intelligence at Scale
How Kubernetes evolved from a container orchestrator to a universal platform for AI workloads.
 Younes Hairej
KubeCon Japan 2025 confirmed a new reality: AI workloads define modern infrastructure, and Kubernetes has become their universal control plane. From Bloomberg's production AI gateway to DaoCloud's multi-host inference serving 651-billion parameter models, the convergence is reshaping the entire stack.
The AI Infrastructure Inflection Point
Models like DeepSeek-R1 require 1.3TB of VRAM in FP16 or 651GB in FP8 just to run-necessitating multiple nodes before performance optimization. This isn't bigger hardware-it's an entirely new infra category.
Tokyo sessions exposed a fundamental shift in AI architecture. Bloomberg's Alexa Griffith demonstrated platform evolution through three distinct eras:
Era | Workload Scale | Input/Output | Data Architecture |
|---|---|---|---|
Traditional | Lightweight | Short, defined JSON | Transactional databases |
Predictive ML | MB-GB | Tensor | Feature stores |
Generative AI | GB-TB | Variable, streamed | Vector databases |
Summary
The GenAI era demands fundamentally different infrastructure. Where traditional apps measured CPU capacity and request throughput, AI workloads require GPU orchestration, token-based rate limiting, and disaggregated serving architectures.
This is where Kubernetes' true power emerges-not just as a container orchestrator, but as the platform for building AI platforms.
The Three Dimensions of AI on Kubernetes
At Aokumo, we see this convergence through three lenses: AI on Kubernetes, AI below Kubernetes, and AI in Kubernetes.
This framing captures how we approach building intelligent, scalable infrastructure across the stack.
1. AI on Kubernetes: Workloads and Applications
AI workloads are ultimately containers with special requirements. All production-grade practices-observability, CI/CD, security-apply directly to inference services and training jobs.
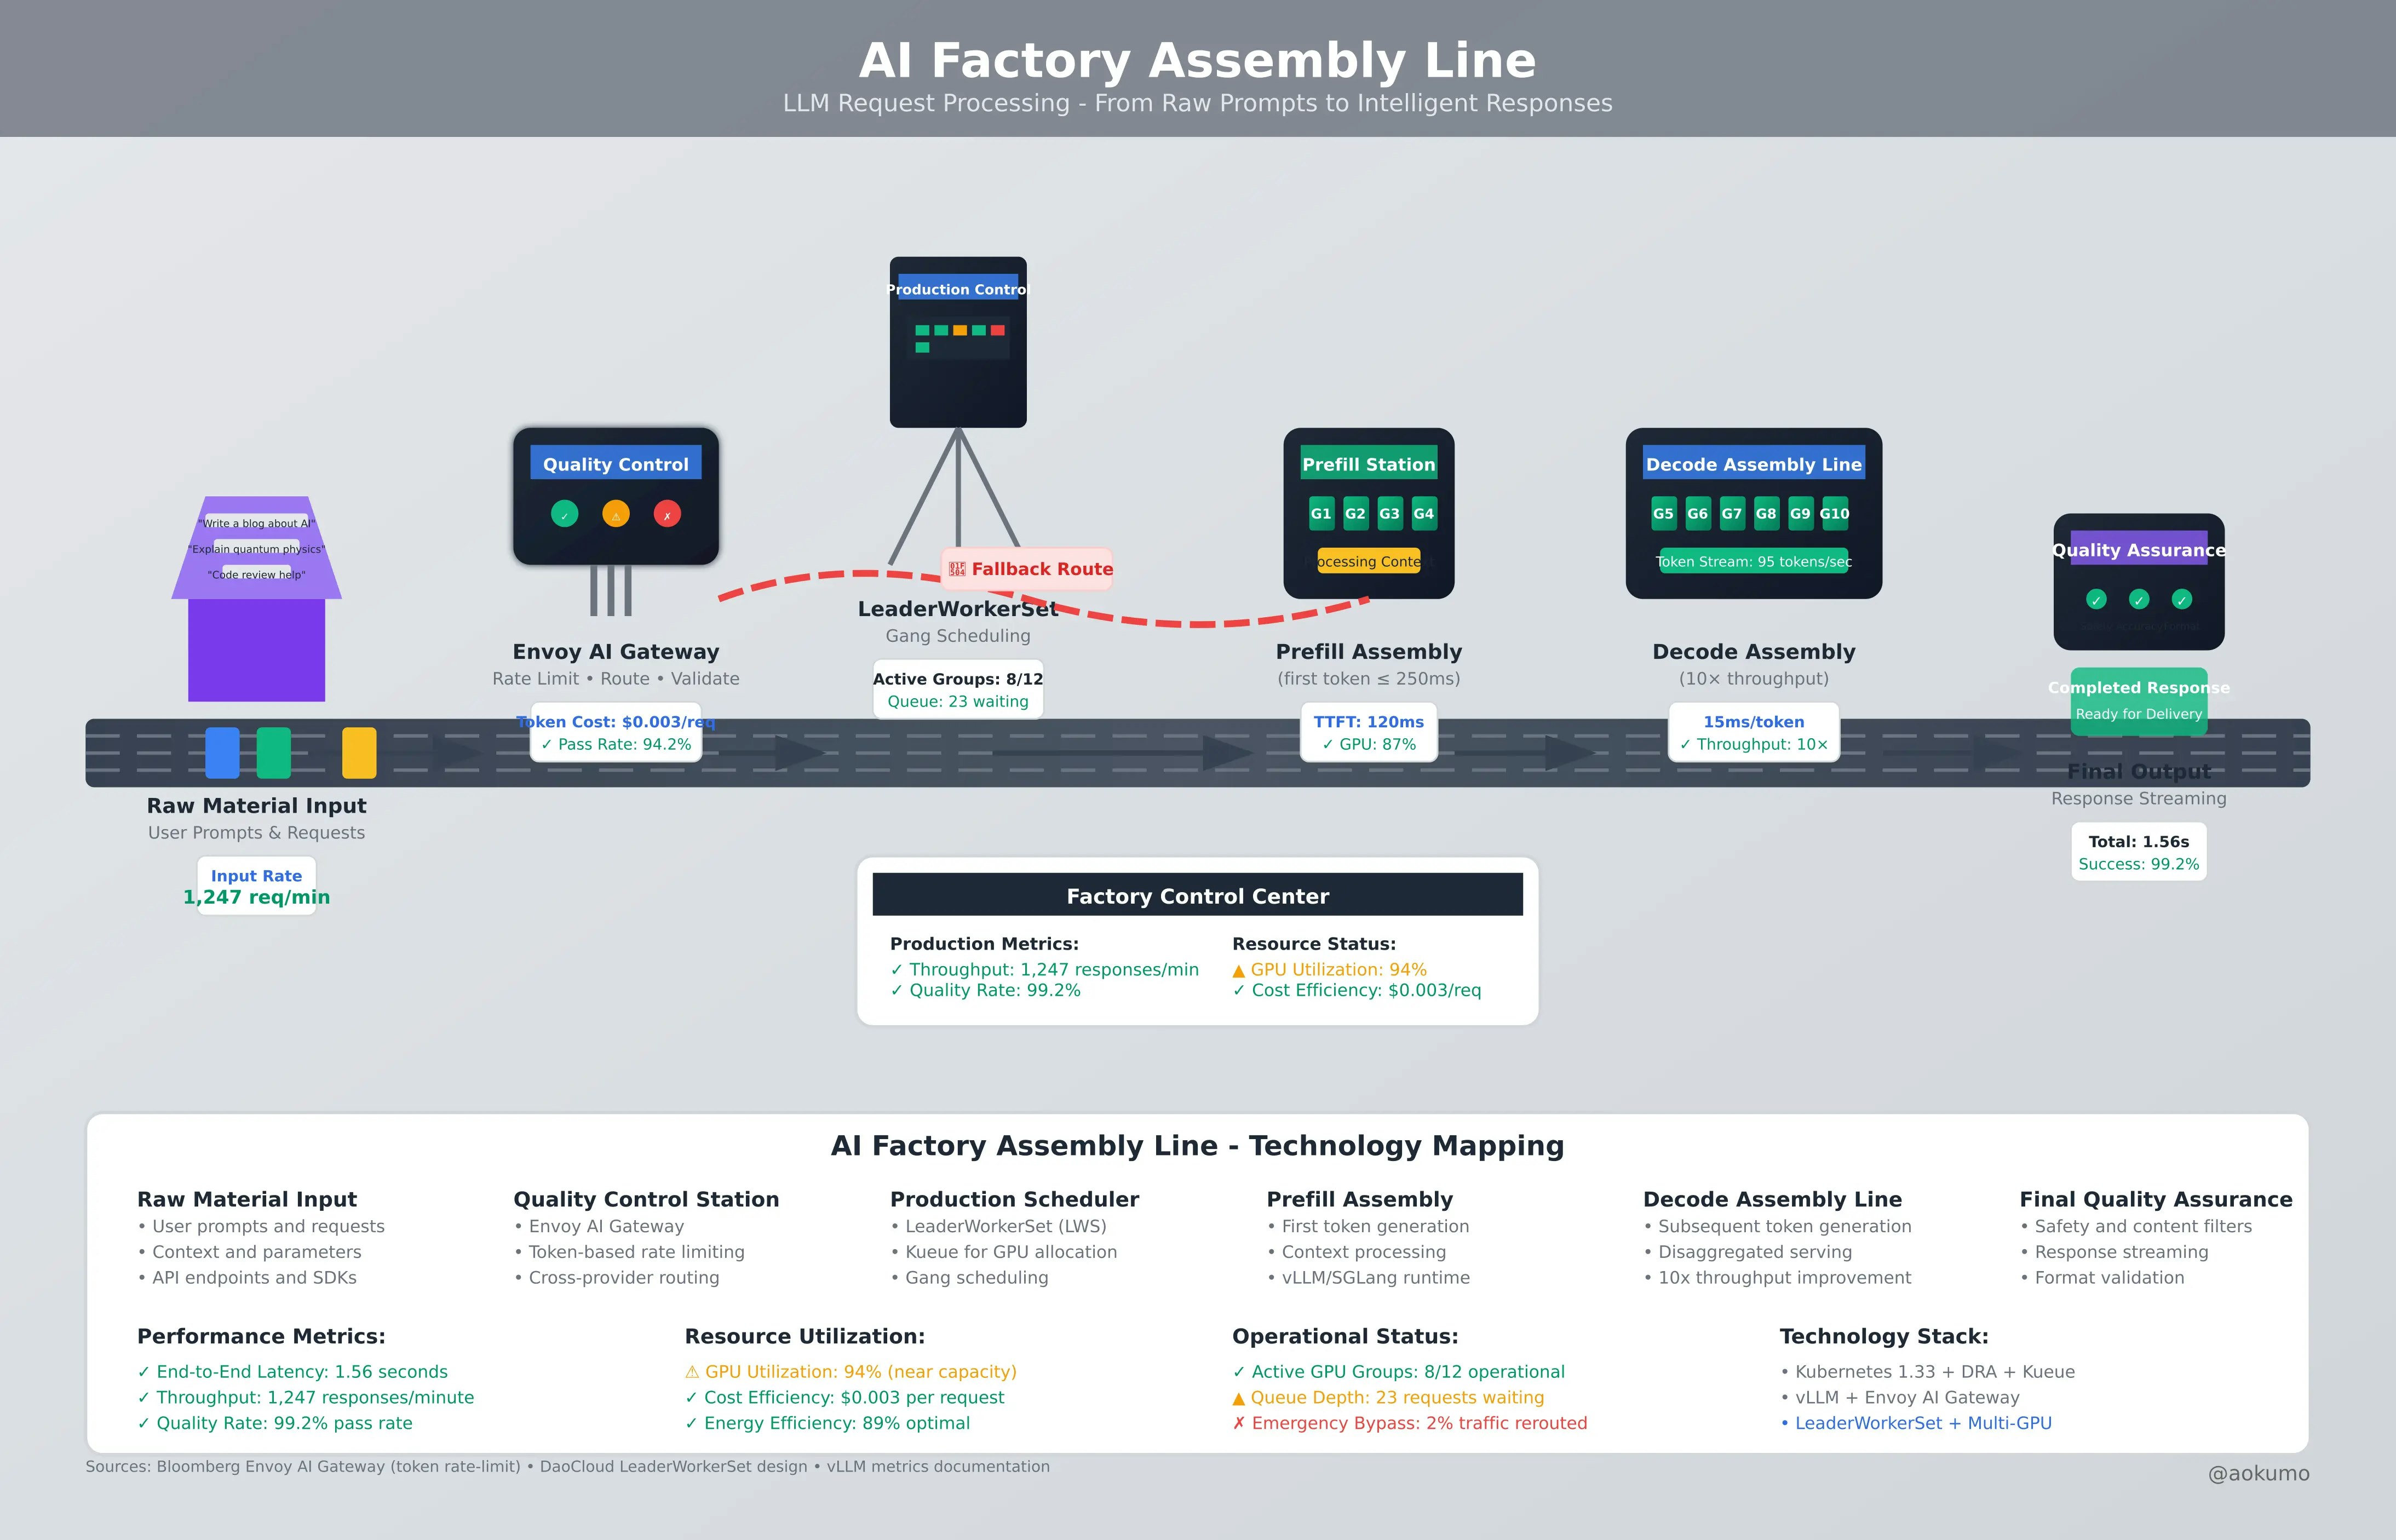
Bloomberg's Envoy AI Gateway handles enterprise LLM traffic with:
- Unified API approach - OpenAI format for any provider (Anthropic, Azure, self-hosted)
- Token-based rate limiting with configurable cost formulas
- Cross-provider fallbacks - self-hosted → AWS Bedrock → Azure OpenAI
- Production observability for LLM request patterns
apiVersion: aigateway.envoyproxy.io/v1alpha1
kind: AIGatewayRoute
spec:
llmRequestCosts:
- cel: input_tokens / uint(3) + output_tokens
metadataKey: tokenCost
rules:
- backendRefs:
- name: azure-backend
priority: 0
weight: 2
- name: openai-backend
priority: 1 # Fallback
Key insight: "Resilience is critical for GenAI system availability. Priority-based fallback for cross-region or cross-model providers." - Dan Sun, Bloomberg
2. AI below Kubernetes: Hardware and Resource Management
Traditional CPU/memory scheduling breaks down when you need disaggregated GPU serving across multiple nodes with complex topology requirements.
DaoCloud's LeaderWorkerSet (LWS) addresses this with:
Multi-host distributed inference patterns:
- Leader-worker topology - one coordinator, multiple GPU workers
- Automatic environment injection - LWS_LEADER_ADDRESS, LWS_GROUP_SIZE
- Gang scheduling - all-or-nothing deployment for large model sharding
- Topology-aware placement - rack-level anti-affinity for fault tolerance
apiVersion: leaderworkerset.x-k8s.io/v1
kind: LeaderWorkerSet
metadata:
name: deepseek-r1-inference
spec:
replicas: 2 # Number of model instances
leaderWorkerTemplate:
size: 8 # 1 leader + 7 workers per instance
restartPolicy: RecreateGroupOnPodRestart
Disaggregated serving architecture delivers 10x throughput improvement (DaoCloud benchmarks, Jun 2025) by separating prefill and decode phases across different GPU pools.
Auto-scaling with AI-specific metrics:
- vllm:num_requests_waiting (recommended over GPU utilization)
- vllm:time_to_first_token_seconds
- vllm:gpu_cache_usage_perc
Check out the vllm documations for details.
3. AI in Kubernetes: Platform Integration
The complete ML lifecycle requires more than inference. Kubeflow's ecosystem evolution demonstrates how Kubernetes becomes the foundation for end-to-end AI platforms:
Training Operator 2.0 with native DeepSpeed support:
- Distributed training across multiple nodes and GPUs
- Framework agnostic - PyTorch, JAX, MLX support
- Integration with Kueue for fair-share GPU scheduling
KServe for production inference:
- Distributed KV cache with LMCache for improved performance
- Envoy AI Gateway integration for unified traffic management
- Auto-scaling based on custom AI metrics
Ray Data solves the data streaming challenge:
- Optimized CPU/GPU usage during large dataset training
- Eliminates wasteful disk I/O from cloud storage
- Streaming interface for distributed GPU nodes
Production Patterns: What Actually Works
Common Gotchas
- CPU-style autoscaling → GPU waste
- No token SLO → hidden queues
- LLM cache mismatch → sudden latency spikes
1. Multi-Cluster AI Orchestration
The pattern: Run AI workloads across multiple clusters for resilience, cost optimization, and geographic distribution.
Implementation:
- Hub cluster with centralized AI gateway and scheduling
- Workload clusters with specialized hardware (GPU types, memory configurations)
- Cross-cluster networking with Cilium ClusterMesh for model federation
2. Capacity-Aware Routing and Autoscaling
The challenge: GPU resources are expensive and scarce. Traditional autoscaling based on CPU metrics fails catastrophically.
The solution:
- Queue depth monitoring - scale based on num_requests_waiting, not utilization
- Token throughput optimization - route requests based on model capacity
- Cost-aware scheduling - balance performance vs. GPU expense
3. Model Lifecycle Management
Beyond just inference: Production AI platforms need:
- Model versioning and A/B testing capabilities
- Canary deployments for model updates
- Rollback strategies when models degrade
- Multi-model serving on shared infrastructure
4. End-to-End Observability
AI-specific metrics that matter:
- Token telemetry - input/output token rates, costs per request
- Prompt lineage - tracking requests through the system
- Hallucination detection - grounding and factuality checks
- GenAI SLOs - time-to-first-token, tokens-per-second
Building Your AI-Ready Platform
Based on the patterns emerging from KubeCon Japan 2025, here's a practical roadmap:
Phase 1: Foundation (Weeks 1-4)
Establish GPU-aware scheduling:
- Deploy Kueue for fair-share GPU allocation
- Configure Dynamic Resource Allocation (DRA) for fine-grained GPU control
- Set up NVIDIA GPU Operator for hardware management
- Implement topology-aware scheduling for multi-GPU workloads
Phase 2: Intelligent Traffic Management (Weeks 5-8)
Add AI-specific networking:
- Deploy Envoy AI Gateway for unified LLM traffic management
- Configure cross-provider fallbacks (self-hosted → cloud)
- Implement token-based rate limiting with cost formulas
- Set up AI-specific observability (token metrics, queue depth)
Phase 3: Advanced Patterns (Weeks 9-12)
Scale to production workloads:
- Deploy LeaderWorkerSet for multi-host model serving
- Configure disaggregated serving for large models
- Implement Kubeflow pipelines for complete ML lifecycle
- Add Ray Data for training data optimization
Phase 4: Platform Integration (Weeks 13-16)
Build developer experience:
- Deploy KServe for production inference serving
- Configure multi-cluster AI orchestration
- Implement model lifecycle management
- Add end-to-end AI observability stack
The Strategic Implications
What makes this transformation significant isn't just the technical capabilities-it's the economic and operational advantages.
Cost Optimization at Scale
- Disaggregated serving increases GPU efficiency by 10x
- Dynamic resource allocation eliminates idle GPU time
- Multi-provider fallbacks reduce vendor lock-in and costs
Developer Productivity
- Unified APIs abstract provider differences
- Kubernetes-native workflows leverage existing CI/CD
- Declarative model deployment simplifies operations
Enterprise Readiness
- Multi-cluster resilience for mission-critical AI workloads
- Compliance and governance through Kubernetes RBAC
- Vendor independence through standardized APIs
Looking Ahead: The AI-Native Platform
The convergence of AI and Kubernetes represents more than technological evolution-it's the foundation for AI-native platforms that will define the next decade of computing.
Key indicators from KubeCon Japan 2025:
- CNCF projects increasingly focus on AI workload patterns
- Enterprise adoption accelerating for mission-critical AI applications
- Standardization efforts around AI APIs and protocols
- Open source innovation driving rapid advancement
The opportunity for platform teams is enormous. Organizations that build AI-ready Kubernetes platforms now will have significant advantages as AI workloads become the primary driver of infrastructure demand.
The question isn't whether your platform will need to support AI workloads-it's whether you'll be ready when they arrive.
Further Reading
- Envoy AI Gateway Documentation - Complete API reference and deployment guides
- LeaderWorkerSet Design Doc - Multi-host inference architecture patterns
- Kubeflow Training Operator 2.0 - DeepSpeed and distributed training support
- KServe 0.15 LMCache Blog - KV cache optimization techniques
- CNCF GPU Working Group - Kubernetes GPU scheduling and DRA patterns
What AI workload patterns are you seeing in your organization? How are you preparing your platform for the AI-native future?
Next in our KubeCon Japan 2025 series: "Edge Computing Revolution: Kubernetes Everywhere" - exploring how cloud-native infrastructure is reaching into factories, vehicles, and IoT devices worldwide.
Let’s explore how we can scale your AI workloads securely and cost‑effectively. Contact us now!