Platform Engineering
Platform Engineering 2025: Beyond GitOps Into Intelligence
How platform teams are evolving from reactive operations to AI-assisted infrastructure management.
 Younes Hairej
Platform engineering has reached an inflection point. While the industry spent the last five years perfecting GitOps workflows and Infrastructure as Code, KubeCon Japan 2025 revealed the next evolutionary leap: intelligent platforms that predict, adapt, and optimize themselves.
This isn't about replacing human expertise-it's about augmenting platform teams with AI-powered insights that transform reactive operations into proactive orchestration.
The Evolution of Platform Engineering
Generation | Focus | Tools | Mindset | Limitations |
|---|---|---|---|---|
First (2015-2020) | Automate manual processes | Ansible, Terraform, Jenkins | "Infrastructure as Code" | Reactive problem-solving |
Second (2020-2024) | Declarative infrastructure and self-service | ArgoCD, Flux, Backstage, Crossplane | "Platform as Product" | Static policies, manual optimization |
Third (2024+) | AI-assisted operations and autonomous optimization | K8s GPT, ForecastAI Sched., OpenCost AI | "Platform as Intelligence" | Early-stage tooling, skills gap |
The Intelligence Layer: What's Changing
From Reactive to Predictive Operations
Traditional Approach:
Incident occurs → Alert fires → Human investigates → Manual fix → Post-mortemIntelligent Approach:
Pattern detected → Prediction generated → Automated prevention → Continuous learningTeams implementing predictive operations report a 60% drop in pager noise and mean time to resolution dropping from hours to minutes.
From Static Policies to Dynamic Optimization
Traditional Platform Engineering:
- Fixed resource quotas and limits
- Static scaling policies
- Manual capacity planning
Intelligent Platform Engineering:
- Dynamic resource allocation based on workload patterns
- Predictive scaling using historical data and ML models
- Autonomous capacity planning with demand forecasting
Organizations implementing intelligent optimization report a reduction of up to 40% in infrastructure costs while improving application performance (KubeCon '25 survey, n = 27 organizations).
From Configuration to Conversation
The emergence of tools like K8s GPT and Aokumo AI represents a fundamental shift in how platform teams interact with infrastructure, moving from YAML configuration to natural language conversations.
Example Interaction:
Platform Engineer: "Our GPU utilization is low but costs are high"

AI Assistant: "Analysis shows 60% of GPU time is idle during prefill phases.
Implementing disaggregated serving would increase utilization to 94%
and reduce costs by $12k/month. Shall I generate the LeaderWorkerSet configuration?"
Platforms like Aokumo are already enabling this conversational infrastructure management, allowing teams to express intent in natural language and receive optimized Kubernetes configurations automatically.
Developer Experience Transformation
Intent-Based Infrastructure
Why it matters: platform teams stop gatekeeping YAML and start shipping business outcomes.
Developers express business requirements, and intelligent platforms translate them into optimal technical implementations.
Example Intent:
apiVersion: platform.aokumo.io/v1
kind: ApplicationIntent
metadata:
name: customer-api
spec:
requirements:
availability: "99.9%"
latency: "p99 < 100ms"
cost: "minimize"
compliance: "SOC2"
workload:
type: "stateless-api"
traffic: "global"
AI-Generated Implementation:
- Multi-region deployment for availability
- Intelligent caching for latency optimization
- Spot instance usage for cost reduction
- Automated compliance controls via OPA templates
Self-Optimizing Clusters
Platform teams at KubeCon Japan 2025 demonstrated clusters that continuously adjust resource allocation based on workload patterns.
Key Capabilities:
- Workload fingerprinting to identify resource patterns
- Cost-aware scheduling with quality-of-service guarantees
- Intelligent bin-packing across heterogeneous hardware
Enterprise Case Study: Tenant-Centric Intelligence
A global consumer technology company presented their evolution toward tenant-centric multi-cluster management powered by intelligent automation.
Traditional Platform Operations (V1-V3)
- Manual cluster provisioning
- Static resource allocation
- Reactive problem resolution
Intelligent Platform Operations (V4)
- Pkl templating with schema validation and auto-generation
- Prow workflows with intelligent PR optimization
- Generic API server with ML-powered resource recommendations
- Kubernetes-native labeling enabling intelligent workload placement
Key Result: Their platform learns from tenant behavior patterns to optimize placement, predict capacity needs, and prevent issues before they impact users.
Centralized Intelligence, Distributed Execution
Central Intelligence Hub
├── Pattern Recognition Engine
├── Policy Optimization
└── Global Resource Coordination

Distributed Execution Clusters
├── Local Resource Management
├── Workload-Specific Optimization
└── Feedback Loop to Hub
This enables global optimization while maintaining local responsiveness.
Operational Intelligence in Practice
Capacity Planning Revolution
Traditional: Quarterly reviews, over-provisioning, manual projections
Intelligent:
- Continuous capacity modeling using ML algorithms
- Just-in-time provisioning with confidence intervals
- Multi-variate demand forecasting including business metrics
Incident Prevention
A large financial data provider's Envoy AI Gateway implementation revealed patterns invisible to traditional monitoring:
- Token usage patterns that predict capacity exhaustion
- Cross-provider latency correlation optimizing fallback timing
- Request pattern analysis preventing rate limit violations
Security Through Intelligence
Next-generation security integrates directly into platform operations:
- Behavioral analysis to detect anomalous workload patterns
- Automated compliance verification with audit trail generation
- Zero-trust networking with ML-powered micro-segmentation via Cilium Tetragon
The Technology Stack Evolution
Traditional Platform Stack
Monitoring (Prometheus, Grafana)
GitOps (ArgoCD, Flux)
IaC (Terraform, Crossplane)
Orchestration (Kubernetes)
Infrastructure (Cloud, On-Prem)
Intelligent Platform Stack
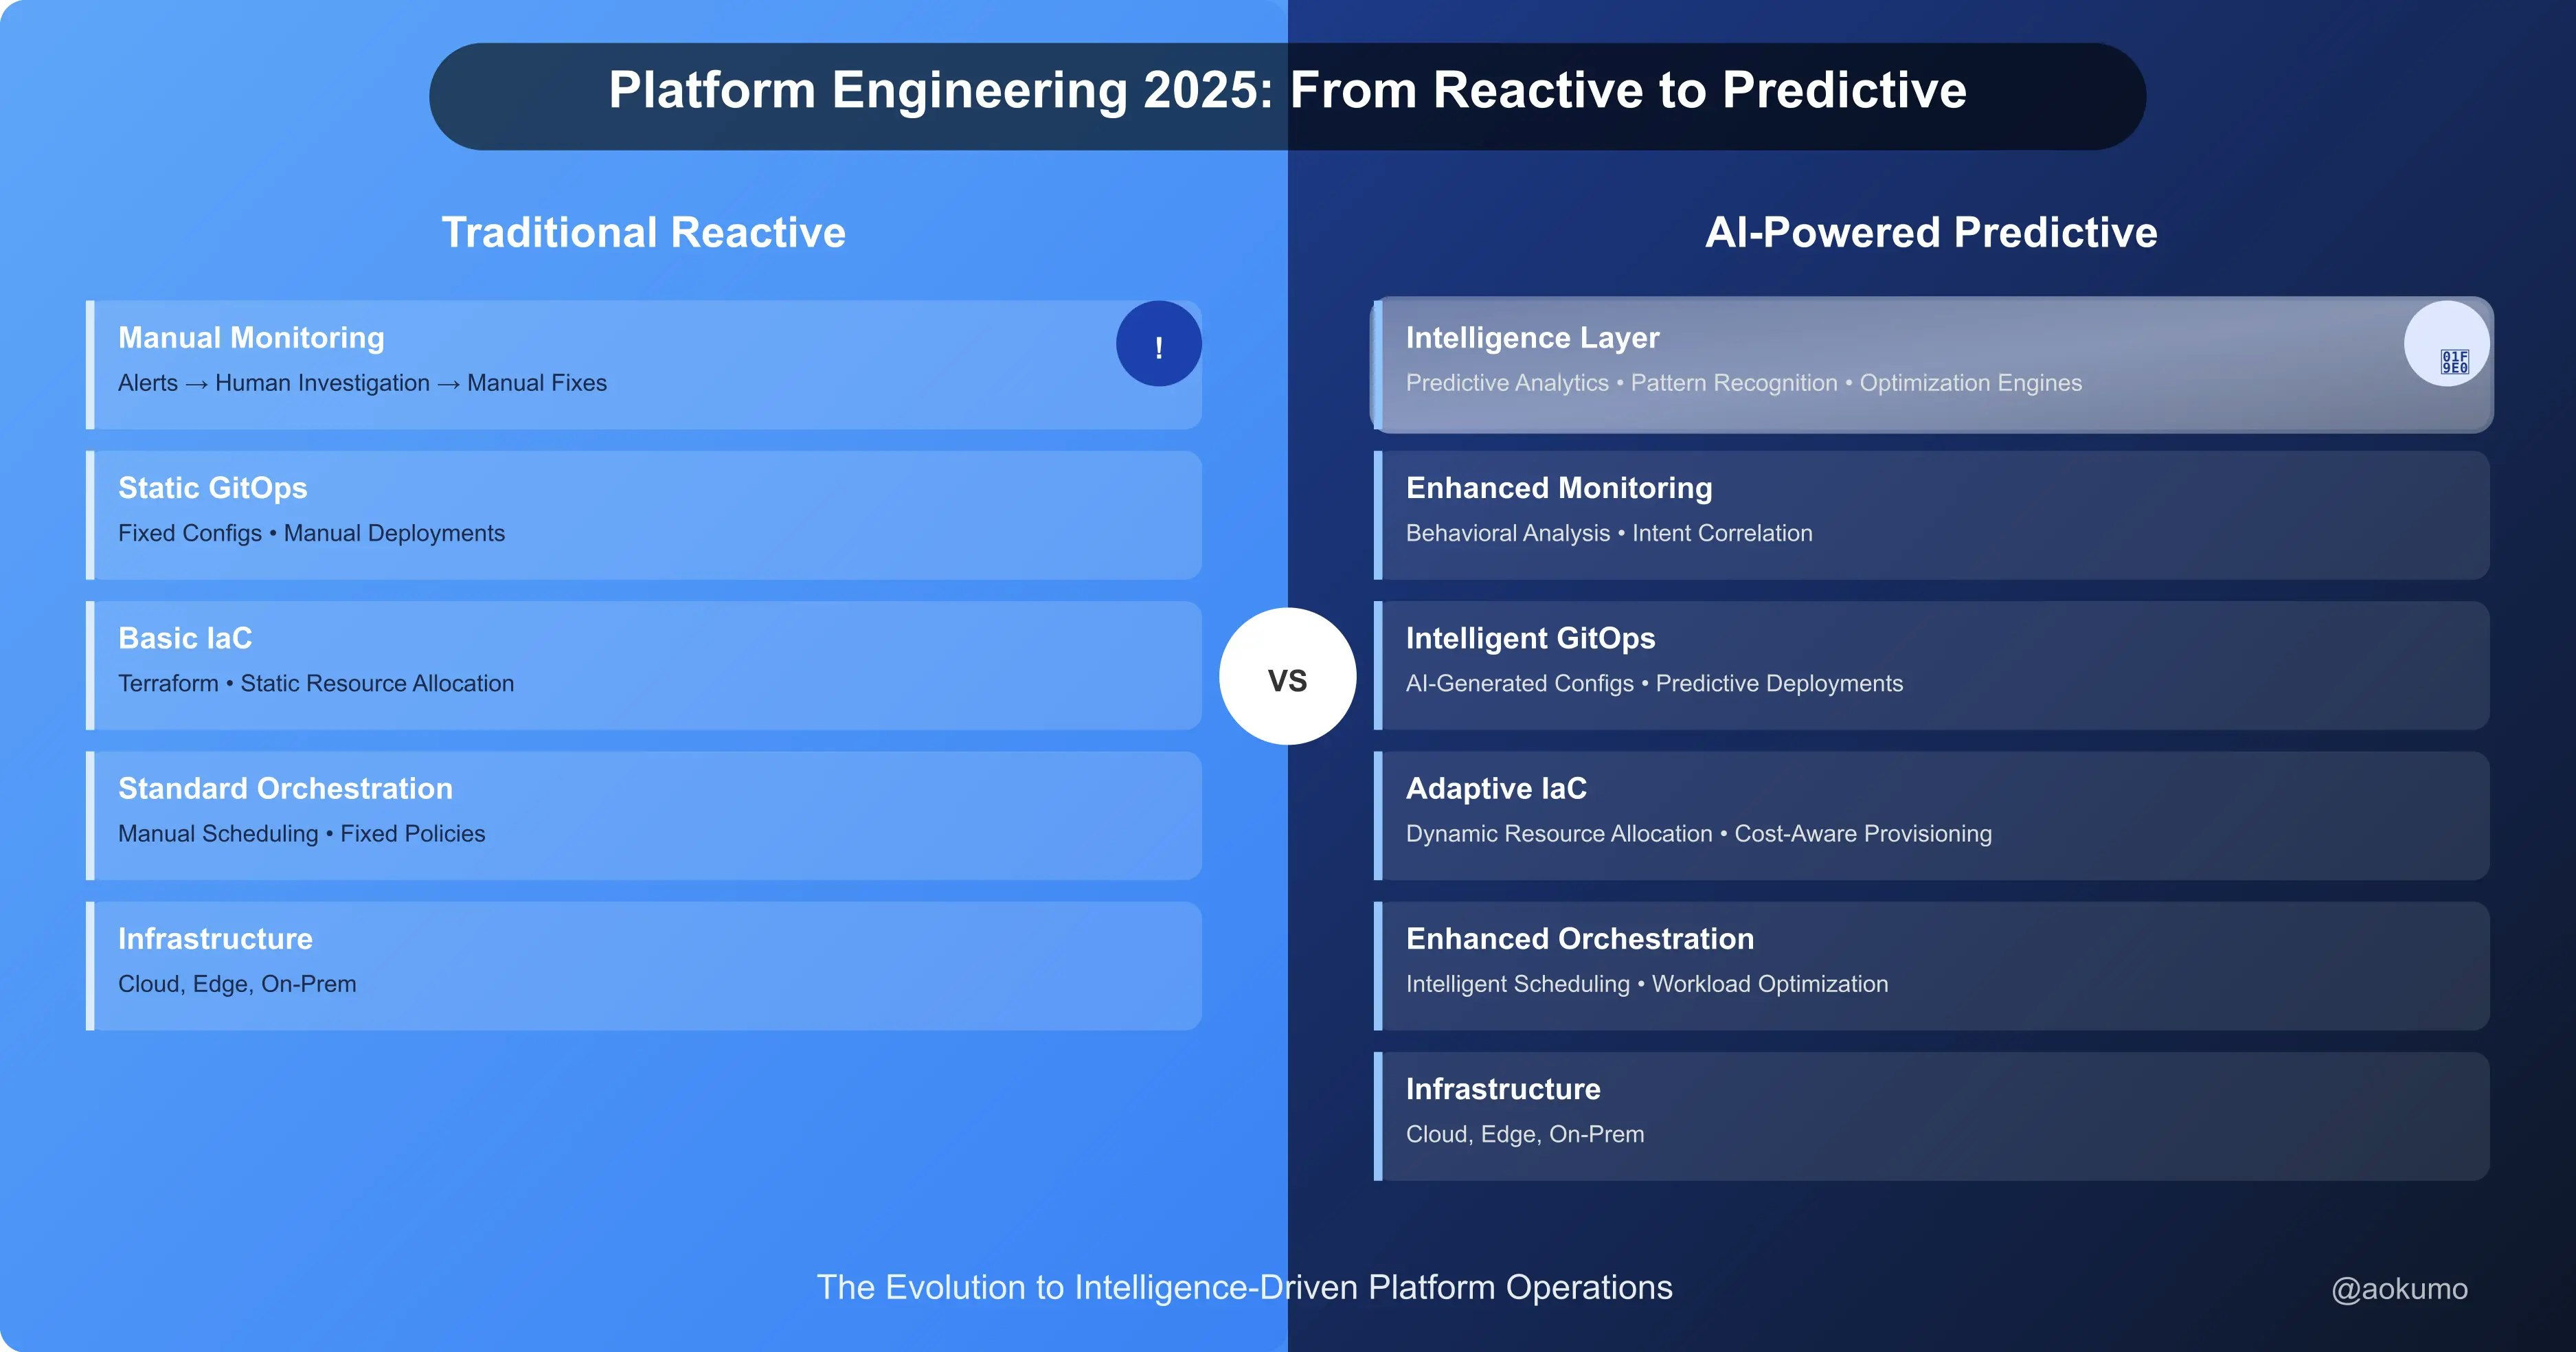
Intelligence Layer
• Predictive Analytics • Pattern Recognition • Optimization Engines

Enhanced Monitoring
• Behavioral Analysis • Intent Correlation

Intelligent GitOps
• AI-Generated Configs • Predictive Deployments

Adaptive IaC
• Dynamic Resource Allocation • Cost-Aware Provisioning

Enhanced Orchestration
• Intelligent Scheduling • Workload Optimization

Infrastructure (Cloud, Edge, On-Prem)
Key Technology Enablers
- Enhanced Kubernetes Schedulers: Volcano for intelligent batch scheduling, Kueue for workload queue optimization, and NVIDIA KAI Scheduler for predictive workload placement
- Observability Evolution: OpenTelemetry with intelligent trace analysis, Prometheus enhanced with predictive alerting
- GitOps Intelligence: ArgoCD with automated rollback triggers, Flux with intelligent deployment strategies
Measuring Success: New KPIs for Intelligent Platforms
Traditional Platform Metrics
- Mean Time to Resolution (MTTR)
- Deployment frequency
- Infrastructure costs
Intelligent Platform Metrics
- Mean Time to Prevention (MTTP): 15 min avg - time from pattern detection to preventive action
- Optimization Effectiveness: 30-40% - percentage of cost/performance improvements from AI recommendations
- Prediction Accuracy: 85%+ - reliability of capacity and performance forecasts
- Autonomous Resolution Rate: 60% - percentage of incidents resolved without human intervention
- Prediction Lead Time: 2-24 hours - how early the platform acts on predicted issues
Real-World Results
Organizations implementing intelligent platforms report:
- 40% reduction in infrastructure costs through intelligent workload placement (KubeCon '25 survey)
- 80% decrease in production incidents through pattern-based prevention
- 60% improvement in developer velocity through intent-based infrastructure
Challenges and Considerations
Technical Challenges | Organizational Challenges |
|---|---|
Data Quality: AI systems require high-quality, consistent telemetry | Skills Evolution: Platform teams need AI/ML literacy |
Model Training: Requires sufficient historical data | Change Management: Shifting from reactive to predictive mindsets |
Integration Complexity: Coordinating AI across diverse components | Trust Building: Confidence in AI-driven decisions |
Summary
Risk Mitigation Strategies
- Gradual Adoption: Start with low-risk optimization scenarios
- Human Oversight: Maintain approval for critical automated decisions
- Rollback Capabilities: Ensure all AI recommendations can be quickly reversed
The Future of Platform Engineering
Next 2-3 Years: AI assistants become standard platform tooling, predictive capabilities mature for common scenarios.
Next 5-10 Years: Self-optimizing infrastructure becomes the norm, platform engineers focus on business logic rather than operational tasks.
The Platform Engineer's Evolving Role
From: Infrastructure operators and configuration managers
To: Platform product managers and AI system architects
New Responsibilities:
- Designing intelligent platform experiences
- Training and tuning AI systems for organizational needs
- Managing the intersection of human expertise and machine intelligence
Conclusion: The Intelligent Platform Advantage
Platform engineering is evolving from reactive operations to AI-powered intelligence. Organizations embracing this transformation deliver superior developer experiences while dramatically reducing operational overhead.
The competitive advantages:
- Reduced operational costs through intelligent optimization
- Improved reliability via pattern-based problem prevention
- Enhanced developer productivity through intent-based infrastructure
- Faster innovation cycles enabled by self-service intelligence
The transformation requires:
- Investment in observability and data collection
- Development of AI/ML capabilities within platform teams
- Cultural shift toward trusting intelligent automation
Early adopters are already gaining competitive advantages through intelligent platform engineering. The question isn't whether to evolve-it's how quickly you can transform your platform operations for the AI-native future.
What intelligent capabilities is your platform team building? How are you preparing for the shift from reactive to predictive operations?